Every cluster over a year old has them. A PersistentVolumeClaim in a namespace nobody owns any more, bound to a 500 GiB gp3 volume, attached to nothing, billed every hour since the Deployment that used it was torn down in a migration. Kubernetes deliberately refuses to garbage collect that claim, because guessing wrong about storage means destroying data. So the cleanup job lands on you, and until now the only way to find unused PVCs at scale was to write something: pull every PVC, pull every Pod, join on spec.volumes[].persistentVolumeClaim.claimName, then join that against a cloud billing export to work out which ones are worth the argument.
Kubernetes v1.37 makes that join unnecessary. The v1.37 release blog on PVC last-used time, published 21 September 2026, confirms that the PersistentVolumeClaimUnusedSinceTime feature gate has graduated to beta and is on by default. The API now tells you directly whether anything is using a claim, and when that stopped being true. Orphaned volumes become a query instead of a project, which is the first time Kubernetes storage cost work has had a native signal behind it.
What the feature actually adds
The PersistentVolumeClaim protection controller, the same controller that already holds the kubernetes.io/pvc-protection finalizer to stop you deleting a claim out from under a running Pod, now also writes an Unused condition into status.conditions on every PVC. It already watches Pods for the finalizer logic, so it knows the answer; v1.37 just writes the answer down.
The condition object looks like this:
{
  "type": "Unused",
  "status": "True",
  "reason": "NoPodsUsingPVC",
  "message": "No pods are currently referencing this PVC",
  "lastTransitionTime": "2026-09-14T12:03:11Z",
  "lastProbeTime": null
}
status: "True" with reason NoPodsUsingPVC means nothing non-terminated references the claim. When a Pod picks it up, the controller flips the condition to status: "False" with reason PodUsingPVC. There is no separate top-level timestamp field, and this is the detail most of the early write-ups got wrong: the "since when" lives in the condition's own lastTransitionTime. If you see a blog post querying .status.unusedSince, close the tab.
The gate landed as alpha in v1.36 and is beta in v1.37, which is the usual shape of a storage KEP (KEP-5541, owned by SIG Storage). Beta and on by default means you get it on managed control planes as soon as your provider ships 1.37, without an API server flag. It also means the semantics can still change before GA, so treat it as an input to a human decision rather than the trigger for an automated kubectl delete. If you want the wider picture of which controller does what here, our breakdown of the Kubernetes control plane and its controllers covers where the PVC protection controller sits. Elsewhere in the same release, DRA extended resource support went GA.
Reading the condition
For a single claim, the JSONPath filter from the upstream docs is the short version:
kubectl get pvc my-data -o jsonpath='{.status.conditions[?(@.type=="Unused")].status}'
For a fleet-wide view, custom columns get you a table you can eyeball:
# one line; the JSONPath filter picks the Unused condition out of the array
kubectl get pvc -A -o custom-columns='NS:.metadata.namespace,NAME:.metadata.name,UNUSED:.status.conditions[?(@.type=="Unused")].status,SINCE:.status.conditions[?(@.type=="Unused")].lastTransitionTime'
An empty UNUSED column is not the same as False. It means the controller has not written a condition for that claim yet, which you should expect on a freshly upgraded cluster and on claims that have not changed usage state since the upgrade. Give the controller time before you conclude anything from a blank.
Three semantics matter more than the syntax, and the upstream post is explicit about all three. A Pod in phase Succeeded or Failed does not hold the condition at False, so a completed Job releases its claim immediately. A Pending Pod does hold it, including one that is unschedulable and will never run. And where several Pods share a claim, the condition only goes to True once the last non-terminated Pod is gone.
Building a cleanup workflow around it
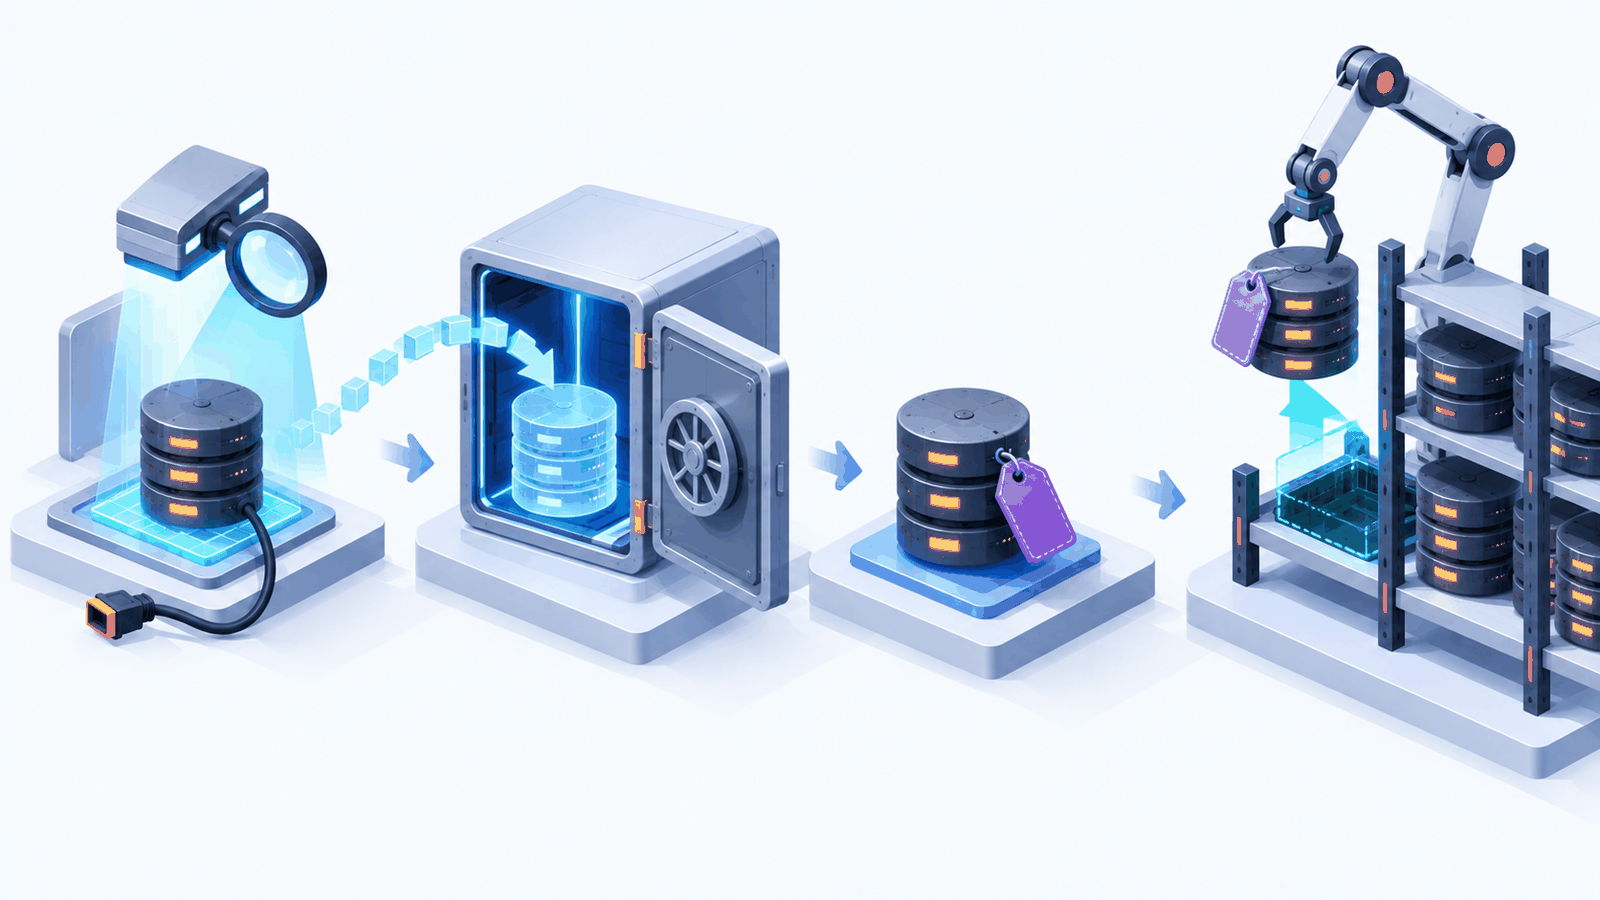
The condition is a filter, not a decision. Here is the sequence I would run.
Find candidates over a threshold. The list of unused PVCs is only useful once you age it. Thirty days is a reasonable starting point for production namespaces, seven for anything labelled as ephemeral or preview.
kubectl get pvc -A -o json \
  | jq -r --argjson days 30 '
      .items[]
      | . as $pvc
      | (.status.conditions // [])[]
      | select(.type == "Unused" and .status == "True")
      # lastTransitionTime is the only timestamp; there is no unusedSince field
      | select((now - (.lastTransitionTime | fromdateiso8601)) > ($days * 86400))
      | "\($pvc.metadata.namespace)\t\($pvc.metadata.name)\t\(.lastTransitionTime)"'
Check for a snapshot before anything else. Query VolumeSnapshots in the namespace and confirm either that a recent one exists with the PVC as its source, or that your backup tool has the volume in a restorable set. If neither is true, take a snapshot first and let it complete. A snapshot costs a fraction of the live volume and buys you the ability to be wrong.
Label, do not delete. Mark the claim and leave it alone for a full notice period. Labels cannot hold RFC 3339 timestamps because of the colons, so put the flag in a label and the date in an annotation:
kubectl label pvc my-data -n analytics \
  storage.example.com/cleanup-candidate=true

kubectl annotate pvc my-data -n analytics \
  storage.example.com/unused-since='2026-08-14T09:21:04Z' \
  storage.example.com/delete-after='2026-10-14'
Know what deletion will actually do. Deleting the PVC is not the same as deleting the data, and the difference is the PV's persistentVolumeReclaimPolicy. Under Delete, which is what a dynamically provisioned volume inherits from its StorageClass unless the class sets reclaimPolicy: Retain, removing the claim removes the backing disk and the cloud spend with it. Under Retain, the PV goes to Released and keeps billing, so you have stopped nothing until you delete the PV and the underlying disk too. Statically provisioned volumes are almost always Retain, which means the tidiest-looking cleanup in a legacy namespace can produce exactly zero savings.
Where the unused PVC condition will mislead you
Situation | What the condition says | What is actually true | What to do |
|---|---|---|---|
CronJob or batch Job between runs |
| Claim is live and needed on the next schedule | Exclude namespaces or claims carrying batch ownership labels; compare the age against the schedule interval |
StatefulSet scaled to zero |
| Data belongs to a replica that will come back on scale-up | Check for an owning StatefulSet before acting; also check its |
Rolling update or node drain | Brief | Nothing is wrong | Any threshold longer than a few minutes filters this out on its own |
Pod stuck |
| Workload is effectively gone | Investigate the stuck Pod; the claim will not surface as a candidate until it clears |
Unschedulable Pod parked on the claim |
| Nothing is running and nothing will | Fix or delete the Pod, then let the condition settle |
Dev or sandbox namespace |
| Often correct, occasionally someone's in-progress work | Shorter threshold, but route the notice to a human owner rather than deleting on a timer |
The condition answers one question well: is any non-terminated Pod referencing this claim right now, and since when. It knows nothing about whether the bytes matter. A claim that has been idle for 200 days might hold the only copy of a compliance dataset. It also does not see consumers outside the Pod API: an external process reading a Retain-policy volume directly, or a CSI driver mounting it out of band, is invisible here. Snapshot before delete is not belt and braces, it is the actual control.
A policy you can defend
Pick one threshold per namespace class and write it into the namespace labels so the query needs no special cases: 7 days for preview and sandbox, 30 for staging, 90 for production. Run the query weekly, not continuously, because weekly cadence forces batching and batching forces review.
Then split approval by blast radius. Anything in a preview namespace with a completed snapshot gets deleted by the platform team on the notice expiry, no ticket. Anything in staging or production needs the namespace owner's sign-off recorded against the annotation, and anything whose PV is Retain needs a second person, because that one requires deleting the underlying disk by hand and there is no undo. Claims owned by a StatefulSet are excluded from automation entirely until somebody confirms the set is not coming back.
The measurable win is not a deletion count. It is that the unused PVC backlog stops growing, because the weekly report now has a number in it that anyone can read, instead of a script only one engineer understands. More patterns for managing cluster state at scale live in our Kubernetes section.